
Solution
AI Data Readiness
Prepare governed, well-described data for AI and prove it was handled properly.
This usually lands on someone's desk when…
Board mandate - An AI mandate arrives from the board, with a timeline attached and no inventory of the data it will run on.
Results nobody trusts - A model has produced results nobody trusts, and no one can say precisely which files went into it.
Security asks - The security team asks what exactly got fed to the LLM, and the honest answer is that nobody kept a record.
Curation never ends - Assembling the dataset for one project took months by hand, and there are five more projects behind it.
The problem, in cost and risk terms
Right now you cannot easily optimize or prove what you fed it.
AI and ML initiatives stall or produce unreliable results because the file data needed for them is scattered across vendors and locations, is poorly labeled, and is full of duplicate, stale, or irrelevant noise that erodes accuracy and inflates compute cost.
Teams lack the ownership, provenance, and version history needed to trust a dataset, and manually curating the right data for each project takes months, which does not scale as AI use cases multiply.
Feeding ungoverned data into an AI model also risks exposing sensitive or regulated information, and creates compliance blind spots that are very hard to detect after the fact.
Who Feels It
Chief Data Officer
Know your data is ready before you build on it.
VP of R&D IT
Let AI work scale without governance becoming the thing that stops it.
Head of Data Science / AI platform
Shorten time-to-usable-dataset from months to weeks.
Security and compliance
Screen for content before it enters a pipeline, not after.
What changes with Starfish
Find the right data. Keep the junk out.
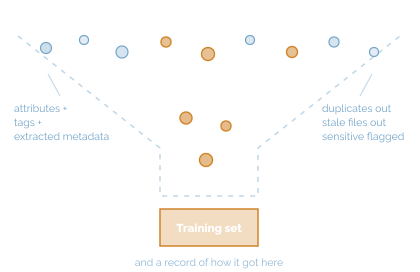
Starfish prepares data for AI at any scale. The catalog’s deep search capability isolates the right data using file attributes, applied tags, and extracted custom metadata together. Summarized graphical reports cover version history, ownership, and location, providing confidence the dataset is trustworthy.
Data is custom-tagged for use and reuse across projects, with movement between readiness stages automated by the Automation Engine. Duplicate detection with MD5 and SHA1 hashing removes exact-duplicate noise before training. Meta-x enriches the catalog with deep internal file metadata across a wide and rapidly expanding catalog of formats. Governance policy enforcement, retention and legal holds, and the movement audit log mean the handling of every dataset is a matter of record rather than recollection.
“Show me the AI story.”
We prepare data for AI and we do not claim the product is AI, because it is not. What we do have is provenance built for scientific reproducibility: every file version carries its own identity and every action is on the record. When someone eventually asks what went into the model, that is the question you will need to answer. Starfish also has a set of MCP endpoints.
Built from these use cases
One outcome, multiple capabilities
Storage Analytics
Turns weeks-long manual audits into on-demand reporting and gives IT a defensible basis for forecasts and budget requests.
Data Movement & Migration
Platform refreshes, cloud adoption, consolidations, and M&A integrations routinely overrun because legacy copy tools cannot move billions of files fast enough.
Chargeback & Showback
Measure and report storage consumption and cost for users, projects, departments, or cost centers, either for visibility (showback) or to allocate costs back to budgets (chargeback).
AI/ML Data Preparation
AI initiatives stall or produce unreliable results because the data behind them is scattered, poorly labeled, and full of duplicate and stale noise.
PROOF
Months → minutes
Normalized inconsistent legacy DICOM tags across a 20-year archive of global-health CT scans, making years of metadata queryable and browsable.
Arizona State University
Center for Evolution and Medicine
“The collaboration between ASU and Starfish tackled challenges in metadata normalization, data governance, and researcher access—ultimately delivering a solution using Starfish that makes complex and voluminous medical imaging data instantly and easily explorable”
- Suhail Ghafoor, Information Technology Manager at the Center for
Evolution and Medicine at Arizona State University.
Seeing is believing
Name one AI project that has stalled.
We will show you what its data actually looks like, including ownership, duplication, sensitive content, and version history, before you spend another GPU hour on it.
Legacy Metadata Made Usable
Months → Minutes
ASU normalised inconsistent DICOM tags across a 20-year archive and let researchers browse it themselves.
Duplicate Data Found
4 PB
Uncovered within a single dataset at a large healthcare client, before any of it reached a pipeline.
Under Management
2.5 exabytes
Capacity under Starfish management across the customer base today.
Customers at Scale
5.8B files over 18PB
5.8 billion files managed per typical customer; 18 PB average for enterprise customers
What teams do instead
Your real alternatives, side by side
Every vendor in this category now makes the curation claim. The differences that survive contact with an auditor are about provenance, scale, and what is in the set.
Dig Deeper
Keep reading before you commit to anything

Case Study
Twenty years of inconsistent DICOM tags, made queryable
How ASU normalised a legacy CT archive and exposed it through virtual directory structures researchers could browse on their own.
7-min read

Blog
Starfish Storage automates dozens of scientific instrument workflows for a leading research hospital
When researcher time was being eroded by having to manually process dozens of instrument data workflows, Starfish Storage stepped in and set researchers free.
5-min read
Glossary
Get everyone using the same words
Storage admins, data owners, and finance can all say “cold data” and mean three different things. The glossary pins each term to one plain definition.
Quick reference
FAQ
Frequently asked questions
We already have this from our storage vendor.
You have it for that vendor. The question is what happens to the files on your other platforms, and what happens when you replace this array. Vendor tools are the reason you cannot answer a question about your whole estate in one place, and they are the mechanism by which the next migration becomes a project or simply locks you in to that vendor.
We can’t afford the disruption of a data management project.
Then do not start one. Start with a read-only scan of one or two volumes, out of band, no agents in the data path, no change to how anyone works. Four to six weeks later you have an aging, ownership, and ROT report. Nothing has moved, and you decide whether there is a business case.
We have scripts that do this.
Most of our customers did too, and the scripts were fine until they were not. The failure mode is always the same: the person who wrote them leaves, or the file count crosses a line and they stop finishing. A biomedical institute we work with replaced a homegrown copy pipeline that had become unmaintainable; the Starfish sequence now completes in 30 minutes on average, with full reporting and history.
What happens to file access when data moves?
Recovery is available through the GUI, the CLI, and, for data owners, inside their own Zone, without a ticket. Where transparency to the user matters, a Starfish script generates soft links so the movement is invisible: Salk’s researchers noticed no difference.
Ready When You Are
Your model is only as good as what you feed it.
Starfish finds the right data, describes it properly, keeps the junk out, and records what happened before it reaches your GPUs.