
Use Case - AI/ML Data Preparation
Governed data,
ready for AI
Starfish discovers, classifies, curates, and delivers files into AI pipelines. Its deep search capability isolates candidate datasets, duplicate detection removes noise before training, and the unique StarfishID versioning plus the movement audit log establish provenance.
Built for teams whose training data is scattered across systems and currently impossible to vouch for.
Isolate
Find the dataset, not the directory
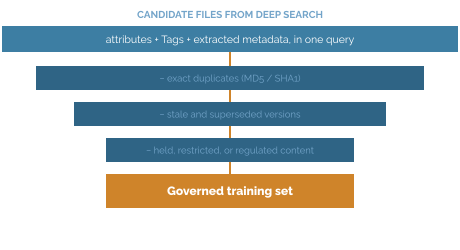
Deep search isolates candidate datasets using file attributes, applied Tags, and extracted metadata together, and Meta-x enriches the catalog with metadata read from inside the files themselves.
One search, three signals
File attributes, applied Tags, and extracted metadata queried together, so a dataset is assembled rather than hunted.
Meta-x enrichment
Internal file metadata from scientific and media formats, including DICOM, HDF5, and BAM, enriches the catalog.
Duplicate noise removed
MD5 and SHA1 hashing removes exact-duplicate noise before training, instead of paying to compute on it.
Less wasted compute
Filtering noise before training shortens time to a usable dataset and cuts the cost of producing it.
Unstructured Data Catalog
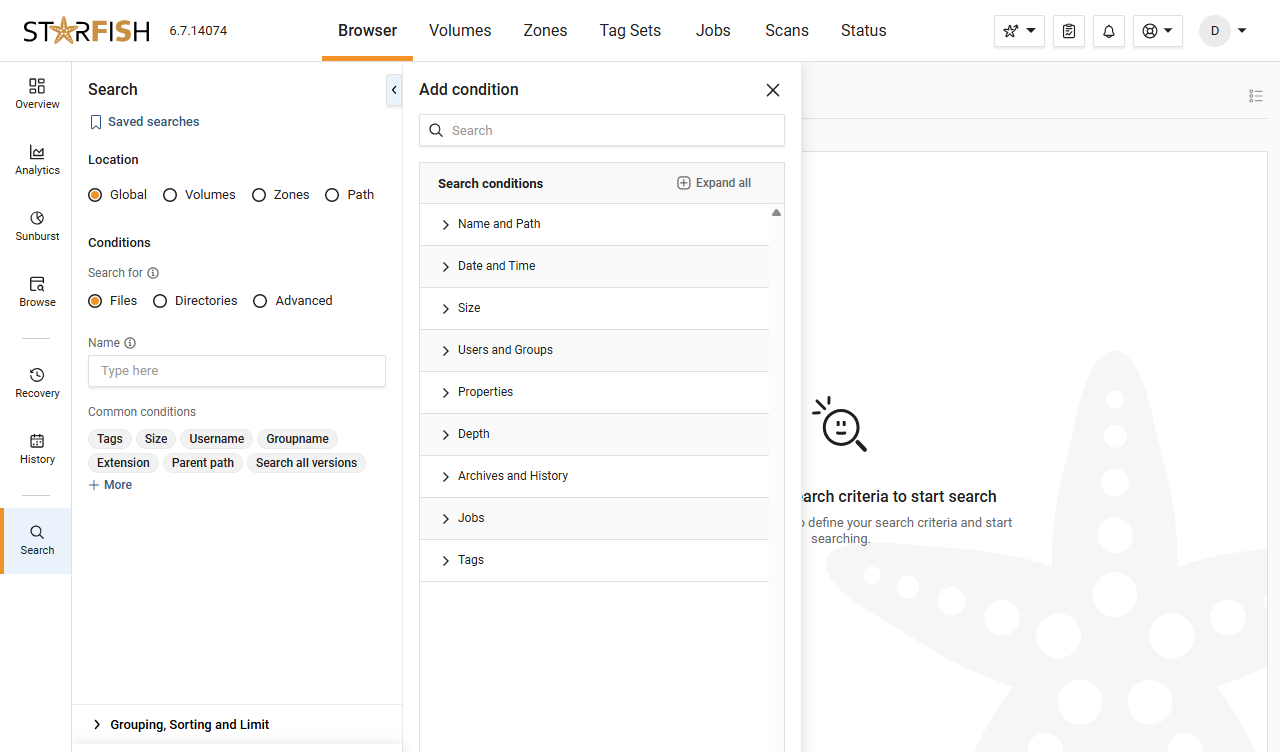
Assemble a real training set from your own file estate
No synthetic demo. We run the search against your environment and show you what a curated candidate dataset looks like.
Govern
Provenance you can actually show
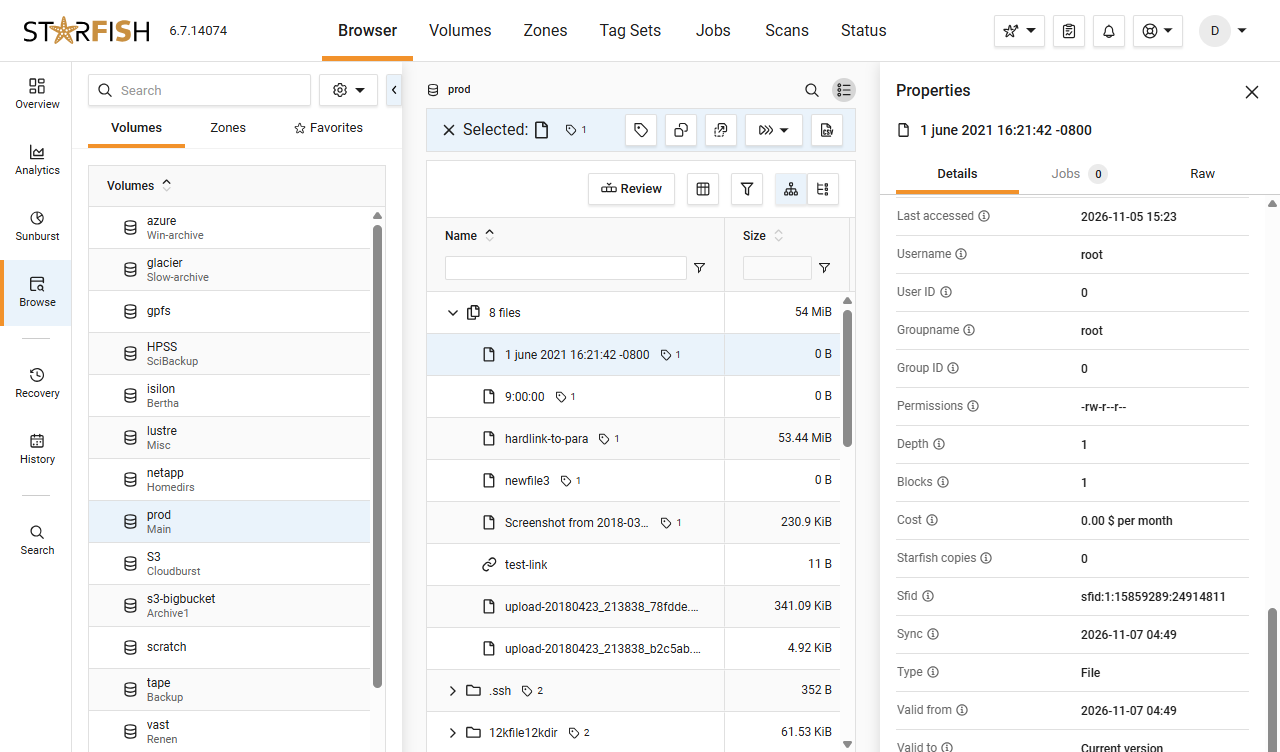
Unique StarfishID (SFID) file versioning and the movement audit log establish where a dataset came from and what has happened to it, with governance policy enforcement, retention, and legal holds applying throughout.
Versioned by SFID
Every file version carries a unique StarfishID, which is what turns “we think this is the dataset” into a record.
A movement audit log
What moved, when, and where to, for when someone asks how a model's training data was handled.
Policy, retention, holds
Governance policy enforcement, retention, and legal holds apply across the pipeline, not just at the start.
Reports on the dataset
Summarized graphical reports cover version history, ownership, and location.
Deliver
Into staging, on policy
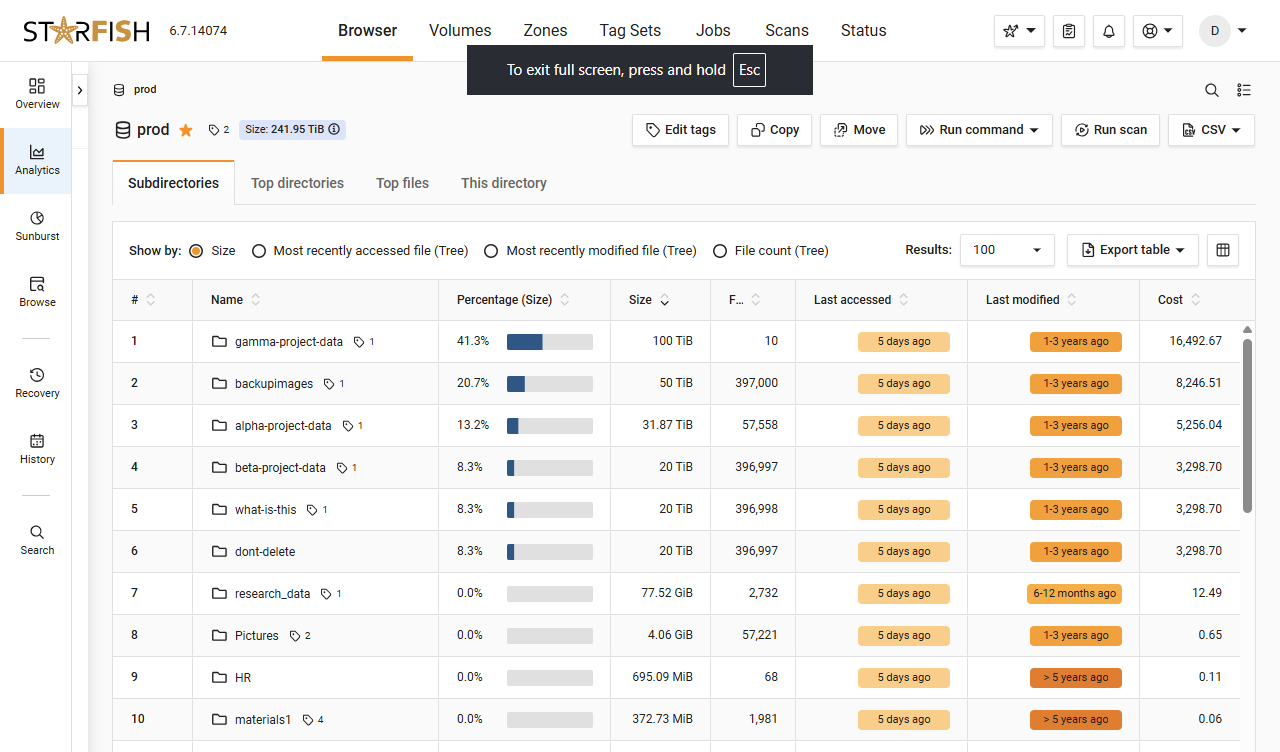
The Starfish Automation Engine automates file movement in and out of project staging areas, and the API and MCP endpoints give pipelines governed access to file metadata without mounting a file system.
Staging in and out
Automated movement into project staging areas, and back out again when the work is done.
Governed access, no mount
The API and MCP endpoints let applications and agents work with file metadata without mounting the file system.
Screened before ingestion
Compliance exposure drops when regulated content is caught before it enters the pipeline rather than after.
Who gets to act
Zones answer who may act on the data - including AI agents that need governed access to file metadata.
In Practice
“The collaboration between ASU and Starfish tackled challenges in metadata normalization, data governance, and researcher access—ultimately delivering a solution using Starfish that makes complex and voluminous medical imaging data instantly and easily explorable”
Suhail Ghafoor, Information Technology Manager at the Center for
Evolution and Medicine at Arizona State University.
Arizona State University
Dig Deeper
Resources for the curious technical reader

Blog
Customer Spotlight: Starfish Storage makes data easier to find, store and protect for Clemson University’s Research Computing and Data Infrastructure team
Clemson Research Computing and Data Infrastructure team shares how they use Starfish to shrink the backup window from a week to less than 24 hours, easily find sensitive files, and empower researchers.
4-min video

Blog
How ASU scratch storage went from instability to control
ASU used Starfish to help researchers stop using scratch storage for permanent archive and bring storage utilization down to 70%
4-min read
Glossary
Get everyone using the same words
Storage admins, data owners, and finance can all say “cold data” and mean three different things. The glossary pins each term to one plain definition.
Quick reference
FAQ
Frequently asked questions
What does AI data preparation involve here?
Discovery, classification, curation, and governed delivery of files into AI pipelines - isolating the right data, removing duplicate noise, establishing provenance, and moving it into staging on policy.
How do you isolate a candidate dataset?
Deep search queries file attributes, applied Tags, and extracted metadata together, so the dataset is assembled from what is true about the files rather than from where they happen to sit.
Why does duplicate detection matter for training?
Exact-duplicate noise erodes accuracy and inflates compute cost. MD5 and SHA1 hashing removes it before training rather than after the bill arrives.
How do we prove where a dataset came from?
Every file version carries a unique StarfishID (SFID), and the movement audit log records what moved, when, and where - supported by reports on version history, ownership, and location.
Can a pipeline work with Starfish without mounting file systems?
Yes. A API underlies everything and a suite of MCP endpoints is available, so applications and agents can work with file metadata in a governed, auditable way.
Is Starfish an AI product?
No, Starfish is a file management platform that includes a suite of MCPs. It prepares governed, well-described file data for AI and records how it was handled.
Ready When You Are
Tell us which dataset you cannot vouch for.
We will curate a candidate set from your own data - not a synthetic demo - and show you the provenance behind it.